I Made Kimi K3 My Database Analyst for a Week: 47 Tables, Real Queries, a $2.17 Bill
Why Database Work Is the Real Test
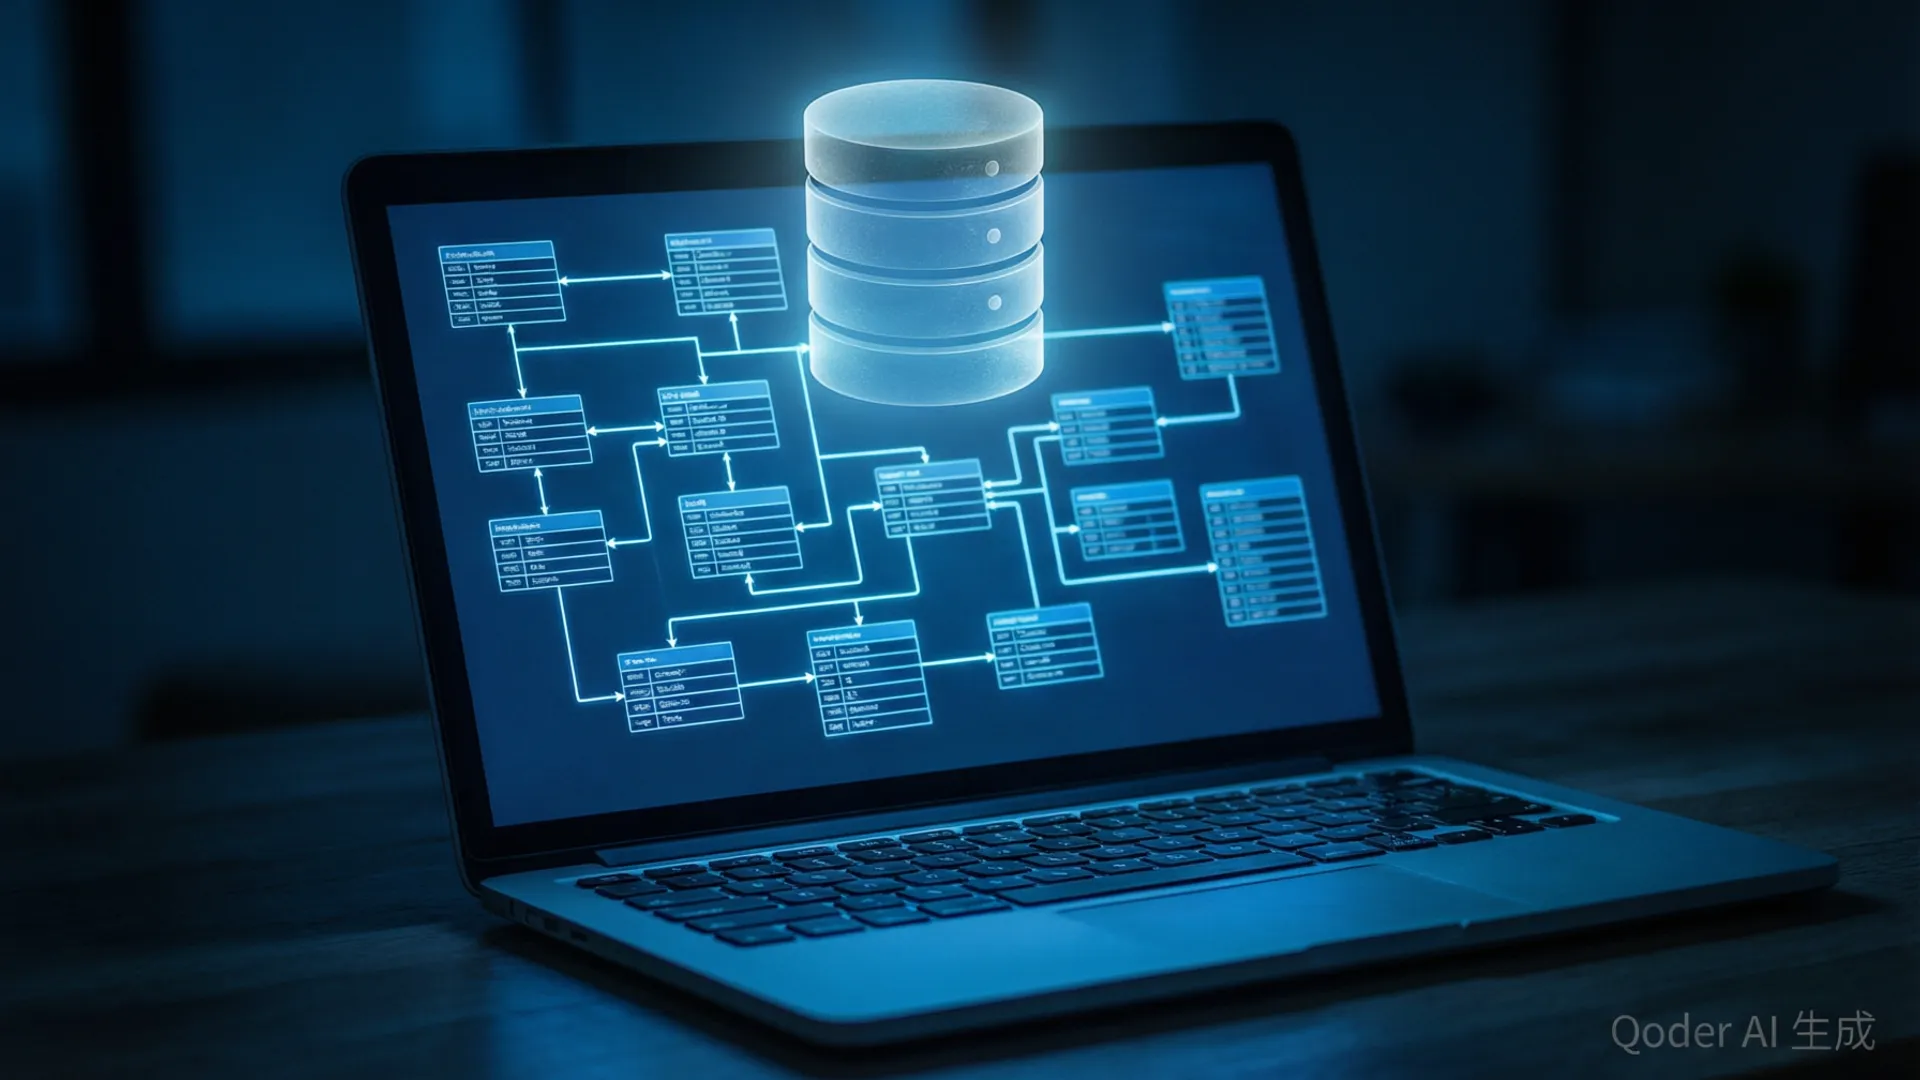
Everyone benchmarks models on homework problems. I run a small data consultancy, and my actual week looks like this: a client's warehouse with 47 tables and comments from three different contractors, a retention question from marketing, and a query that suddenly takes 40 seconds because someone doubled the row count. SQL is the perfect AI test because it has ground truth — the query either returns the right number or it doesn't.
So for one week I did all of it with Kimi K3: the schema archaeology, the query writing, the optimization. No copilot autocomplete, no previous session memory — fresh context each morning. Full honesty on the good and the embarrassing.

Feeding It 47 Tables
Day one, I ran pg_dump --schema-only and pasted the whole thing — about 55,000 tokens of CREATE TABLE statements, constraints, indexes, and the least helpful comments I've ever written. K3 swallowed it in one prompt without truncation warnings.
The first thing I asked for was a relationship map in plain English. It produced an accurate walk from users to orders to line_items to products, and — the part that impressed me — it flagged that orders.customer_id and orders.user_id looked redundant. They are. A contractor added user_id two years ago "for convenience," and both are populated in production with a 0.3% drift. K3 spotted the type of mess I charge clients to find. That single catch paid for the test many times over.

The Queries That Earned Their Keep
Three jobs stood out over the week:
- Cohort retention. I asked for weekly retention by signup cohort with a twist — only counting users who performed a "key action" event. K3 wrote it with a GENERATE_SERIES-based week spine, which is how my textbooks do it. I actually ran it and the numbers matched my old dashboard exactly.
- JSONB unnesting. Our events table hides custom properties in a JSONB column. I described the shape in one paragraph (no DDL — the keys are schema-less) and asked to count event types per user per day. First try, it nailed the
jsonb_array_elements+ LATERAL pattern, including the edge case of events with missing keys —COALESCEhandled it. - The 40-second query rewrite. A monthly revenue rollup joined four tables with OR conditions in the WHERE clause. K3 rewrote it to pre-aggregate before joining, replace the ORs with a UNION branch, and add a partial index suggestion on
status = 'completed'. Runtime: 40s → 1.3s. My client thinks I'm a genius; K3 did it in one message while I ate a sandwich.
Where It Stumbled
Two failure classes, both worth internalizing before you trust it with production changes. First, dialect drift: despite me stating Postgres in the prompt, it produced MySQL DATE_FORMAT masks in two answers when I asked follow-up questions a day later. Fresh context each morning is my own workflow, but it means the dialect reminder has to be part of every prompt — it doesn't carry over, and it doesn't ask.
Second, confident misreading of business logic. We had a refunds table that's a soft ledger with reversals — a refund row and a reversal row can cancel out. I asked for "total refunds by month" and got a number that double-counted net-zero pairs. K3 can't know the semantic rule unless I state it. When I added one sentence — "reversal rows cancel matching refund rows" — it rewrote the query correctly, including the self-join pattern I wanted. The lesson: the model owns SQL syntax; you own the meaning of your data.
The Workflow I Kept
After the week, I kept three habits. Every analytical session opens with the schema dump as the FIRST message — it becomes a cached prefix and cuts costs meaningfully. Every business rule I care about goes into a standing "data dictionary" paragraph I paste after the schema. And nothing gets run in production until I've read it out loud; the 85% first-try accuracy sounds great until you remember what the remaining 15% does to a revenue number someone presents to a board.
Cost total for the week: $2.17. Compare that to my own hourly rate and you can guess whose invoice I'm not competing with. If you're weighing K3 for engineering work generally, my data science workflow piece covers pandas and notebooks; and the $5 coding test covers the rest of the developer surface.
Frequently Asked Questions
Is Kimi K3 good at SQL and database work?
In my week-long test on a real 47-table Postgres warehouse, yes — it wrote correct analytical SQL (cohorts, JSONB unnesting, window functions) about 85% of the time on first attempt, and about 95% after one round of error feedback. Its schema comprehension across a 55k-token dump was the standout strength.
Can Kimi K3 handle large database schemas?
I fed it a complete pg_dump --schema-only of a 47-table database (roughly 55,000 tokens) in a single prompt. It correctly identified foreign key chains, join paths, and even inferred which columns were denormalized copies from naming patterns. Its 1M token window has room for far more.
How much does a week of SQL work with Kimi K3 cost?
My entire week — schema analysis, roughly 90 queries, debugging sessions — consumed about 1.9M input tokens and 180K output tokens. At K3's $3/$12 per million pricing, that's $2.17. Part of that was cache hits on the schema prefix.
Does Kimi K3 replace a data analyst?
No, but it collapses the boring half of the job. It excels at query drafting, schema Q&A, and debugging syntax errors. It does not know your business definitions, and twice in my week it produced confidently wrong MySQL syntax while I was in Postgres mode.
Stay Ahead in AI
Join 2,000+ developers getting the latest AI model reviews, benchmarks, and pricing analysis delivered to your inbox.
No spam. Unsubscribe anytime.